

Building Next-Generation AI Professionals 🚀 Unlocking knowledge, skills & opportunities through blogs, world-class courses, hackathons & a thriving community.
Joined January 2014
- Tweets29.4K
- Following412
- Followers30.1K
- Likes2.4K




Pinned Tweet
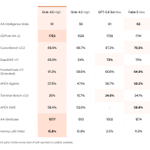
Jev costs $0.044 per 1,000 judgements.
GPT-6 Astra costs $12.182. But cheaper isn't always better: Jev matches on simple evidence checks and trails on harder reasoning.
Best setup? Use both.
analyticsvidhya.com/blog/202… #AIEvals #LLM

Closed-source app. No docs. One AI agent, 7 minutes, $1.83 🕵️
We tested REA, an open-source MCP server for reverse engineering. First we guessed how Obsidian’s quick-switcher ranks results by hand, then let the agent inspect the code.
🎯 It found the scoring function inside a 3.9MB minified file
✅ Our hand-made prediction was right on priority order, even the exact “a word boundary = 10 positions” trade-off
🔍 It also found 4 hidden mechanisms we couldn’t see from outside
⚠️ Its written formula had an off-by-one that only showed up when checked against its own data
Lesson: predict first, then verify.
Full breakdown 👇 analyticsvidhya.com/blog/202…

FDE or AI Engineer?
Both build with AI.
The difference: where you sit, and who owns the system after it ships.
New to the FDE path? Start with our free course: analyticsvidhya.com/courses/… #AICareers #AIEngineer

Your RAG bot can still make things up, even with the source text right in front of it 🫠
Fix: let the LLM write 5 answers, then let JEV (a tiny, cheap checker) ask 4 yes/no questions about each: supported? on-topic? invented details? contradictions?
🚫 Blocked all 16 planted wrong answers
💸 56 checks cost about $0.001
⚠️ But it also blocked ~1/3 of the good answers
🤷 Writing 5 drafts didn't help, the first one was already right
Start with 1 draft + 1 JEV check, then measure before scaling up.
Full breakdown 👇 analyticsvidhya.com/blog/202…

We put Gemini 4 Argon through 4 real tasks 🧪
🎬 8-second product video: nailed it
🌐 Working booking website in Canvas: nailed it
📉 "Conversion fell, roll it back": it spotted that both visitor groups actually improved
📄 8 conflicting launch claims: all labeled correctly, but one invented phrase slipped into the summary 👀
Great at catching traps, still needs a proofread.
Full review 👇 analyticsvidhya.com/blog/202…

OpenAI's new API doesn't chat, it decides 🎯
✅ Yes/no with probability
🧭 Pick from options, with odds
📏 Grade on a rubric
10x faster, $0.10 per 1M tokens, text and images. And it knows when it's unsure: a half-markets, half-regulation headline scored just 52% 😅
analyticsvidhya.com/blog/202…

Your GPU is 99% idle while generating tokens. Yes, really 😳
LLM decode is stuck waiting on memory, not math. The fix is batching:
🚌 Static: waits for the slowest request, one 500-token reply holds up everyone
⏳ Dynamic: starts sooner, still waits to finish
⚡ Continuous: swaps in new requests every single token
Our simulator: continuous batching finished the same work in 41% fewer steps. A 30-token request waited 320 steps on static, exactly 30 on continuous.
Full breakdown 👇 analyticsvidhya.com/blog/202…

We’re giving AI agents our most sensitive data and the power to act on our behalf.
Can anyone explain why a model did what it did? Nope. 😅
Here’s the plan: trust the model the least. A thread 🧵
The checklist:
🔀 Use different models, none grades its own homework
👁️ Log everything in tamper-proof, human-readable form
🧪 Test the failures, not just the wins
🛑 Keep an emergency brake that always works
📢 When things break, tell everyone what failed
Your RAG system confidently answers from the wrong documents. Here's the fix 🔧
Agentic Corrective RAG adds a safety net:
🧐 An LLM grades every retrieved chunk: relevant or not
🔁 Irrelevant? It rewrites the query and searches the web for live info
🧩 Built in LangGraph with Chroma + Tavily, nodes and edges you can follow
Fewer hallucinations, fresher answers.
Full guide 👇 analyticsvidhya.com/blog/202…

Nano Banana 2.1 is here and free for everyone 🍌
We threw 4 tests at it:
📊 Bar chart with exact values: proportions came out spot on
🧱 Clay-style RAG explainer: clean, though one of the "two books" went missing
🖼️ Hawa Mahal as a linocut print: gorgeous style, but it deleted the busy street
💻 Debugging comic: consistent character, unreadable typo
Great for charts and comics. Always check the details you can't afford to lose.
Full review 👇 analyticsvidhya.com/blog/202…

Your LLM judge says "0.995 confident" on every single answer. Useful? Not really 😬
Jev is a tiny judge model with honest probabilities:
💸 277x cheaper and 13x faster than GPT-6 Astra on the CMU study
🎯 Matches it on fact-checking, falls apart on math, code and logic
🪜 Smart trick: trust Jev when it's confident, send only the unsure cases to a bigger LLM. 93.4% accuracy at 41% of the cost
In our test, the one case Jev got wrong was also its lowest-confidence call.
Full comparison 👇 analyticsvidhya.com/blog/202…

Most agent bugs aren't in the answer, they're in the dozens of tiny decisions before it 🎯
Jev turns those into typed choices with probabilities. 10 GitHub repos show what you can build with it:
🌐 Browser agents that pick actions from a table
✂️ Context pruning for coding agents
🔍 A code reviewer that scores severity
🧭 A router that sends easy prompts to cheaper models
Full list + repos 👇 analyticsvidhya.com/blog/202…
We built a real enterprise support agent with Claude Fable 5.1 🏗️
🕵️ 8 prompts: investigation layer, policy RAG, human approval gates, security attacks, multi-tenancy
🚫 Refund limits stayed hardcoded, never an LLM call
💉 Tried a prompt injection hidden in customer text, it stayed just text
🐛 Planted a bug, Claude Code couldn't reproduce it and said so
Full build 👇 analyticsvidhya.com/blog/202…

Tired of retyping the same setup instructions into Claude Code? Turn them into a slash command 🪄
🔒 Mark a skill disable-model-invocation: true so only you can trigger it, never Claude
📁 Scope it personal, project, or just one subfolder
🧩 Example: /new_repo scaffolds backend/frontend/README in one shot
One markdown file, one word, done.
Full guide 👇 analyticsvidhya.com/blog/202…
