

We are @YonksTEAM ● #buildinpublic ● SUPERPOWER = @MrsYonks ❤️🔥uBabe ● ✝️ #Christ believer ● Co-Founder of: @pTokenAssets @WeOwnNet @WeOwnAI @3winSocial
#NoDe (North Denver)
Joined October 2010
- Tweets5.5K
- Following4.7K
- Followers2.6K
- Likes5K




Pinned Tweet
🧵 [1/] What does #ResponsibleAgenticAI look like in practice?
SIMPLE ... prompt ➡️ artifact
(with minimal #HumanInTheLoop / #HITL efforts)
⭐️︱my prompt:
I really liked our WEEKLY PROJECT DOCUMENT in #WeOwnSeason004!! | Time to create PRJ-541 for #WeOwnSeason005 {2026-W41}

yonks|🤖🏛️🪙|Jason Younker retweeted

Meta releases Muse Spark Open, a new SOTA open model.
Run on a Mac Studio via Dynamic 2-bit Unsloth GGUFs.
Muse-Spark-Open-816B-A42B supports text, images, video and audio input with 1M context.
GGUF: huggingface.co/unsloth/Muse-…
Guide: unsloth.ai/docs/models/muse-…


Muse Spark Open -- weights releasing today -- runs great on new Mac Studios thanks to work with @johnternus and Apple.

yonks|🤖🏛️🪙|Jason Younker retweeted
I spent 48 hours in SF hanging out with billionaires, data labs and AI founders and execs running $1B to $100B companies.
My observations:
1. Sooo MANY stories of data brokers making like $2M a WEEK selling company data to labs. I can't tell if it's the beginning or a bubble, and I kept wondering which niches are left. Digging into it actively.
2. At dinner, someone asked the table, "If a new model drops next month, does your company get better or worse?" HALF the table went quiet! I think that's the best question to ask about any AI startup right now.
3. The bar people talk about now is hitting $1B in revenue in 12 months (I guess that's the new unicorn?). What I didn't hear much about is retention. AI revenue can come in fast and leave fast, and I think we're going to see a lot of stories of AI companies with huge revenue and terrible retention.
4. It's pretty clear we're living through the reinvention of the computer. The model is the CPU, the harness is the operating system, and skills and plugins are the apps. Thinking about it that way makes it easier to see where the whitespace is.
5. We're maybe 12 months from an agent that can watch you work for a week and then do your job without any instructions. The screen recording plus agent memory plus local model combination makes this possible right now.
6. Agent harnesses feel like the new GPT wrappers, in a good way, especially vertical ones. The best teams I talked to treat the model as swappable. One founder walked me through routing different models to different jobs: one for taste and visuals, a cheaper one for the everyday stuff, another for text.
They use prompts they can move across models over fine-tuning, and A/B test the output on what users actually do with it: do they edit it, export it, share it? A vertical harness is basically four things: the connectors for that industry's data, evals written by people who know the work, rules for what the agent can and can't touch, and a clean screen for a human to review. The model is maybe 20% of it.
7. There's a lot of reverse engineering going on/cloning going on more than I've ever seen. People are decompiling software and rebuilding it with agents, and someone showed a suite of like 10 apps that are worth $5B+ each all that he cloned open source. Me and everyone are still thinking through what it means when software gets this easy to copy.
8. My guess is the value moves to data. If the software can be rebuilt quickly, what's worth paying for in a legacy SaaS company is the years of customer data and workflows inside it. Some SaaS companies are secretly data companies.
Gets me thinking about how do you truly value data for this saas companies? Like if we were buying these dying saas companies at 2x ARR before (as example), maybe there is a better metric. Idk, just thinking out loud here.
9. It feels like a good chunk of legacy software won't make it to the agentic era, especially anything built around people clicking through a lot of screens.
10. Every company I talked to wants to pipe its internal data into one place and expose it to agents through MCP. Then they look at the data and realize it's a mess: five versions of the same customer, old Slack channels, PDFs nobody can search. Cleaning that up feels like a big consulting opportunity!
11. A lot of founders are building the basic building blocks for agents: APIs, data layers and tools. Some of the companies I saw barely have a UI because the main user is an agent. I really believe the startups that build primitives to this agentic era will do extremely well. Building blocks is the best way to think about it.
12. Labs can get plenty of training data, but it's harder to get real examples of agents failing inside companies. Whoever has those logs has something valuable.
13. Someone running a big consumer company told me the next fight is over memory. The model that remembers the most about you wins, and the smartest model matters less than people think.
14. Physical AI came up a lot. Astra I think was the first model that got people into AI can actually do CAD, and I think a lot of people are thinking what does vibe manufacturing really look like. The line I keep thinking about came from a robotics founder: the hardest problems in AI are deployment problems now, not research problems. Their robots work on their own, call a human when they get stuck, and every one of those calls becomes training data.
15. Cybersecurity companies are having a moment and are actually cool companies to build now, especially the ones that clean up after a breach. Every agent with access to your systems is a new door into your company, and a lot of those doors were left open.
16. Some startups are worth more dead than alive now. A shutdown company with 5 years of Slack, email and code can get paid for licensing all of it. I wouldn't be surprised if founders start factoring that into when they shut down.
17. People are starting to talk about monetizing the agent web. It feels really early, but when the most popular user of the internet is an agent, what startups should you be building?
18. I think agent insurance is coming. Once an agent makes an expensive mistake, insurers will want audits before they cover anyone.
19. Several people said the hire they want most is someone with taste who can write evals. The models are getting good at generating ideas, so the hard part is judging which ones are good.
20. New trend I observed: startup raises VC, uses venture dollars to become a creator, startup fails, founder falls back on being a full-time creator and incubates other products bootstrapped.
21. Getting SIGNIFICANT distribution is HARD right now. Founders are sponsoring buses, buying billboards like crazy and throwing parties with famous DJs to get noticed. Kinda feels dotcom era in that sense.
Attention is what's scarce! The growth guy going viral sharing his UGC strategy from Wispr Flow is a good example. It's the sauce everyone wants, and I truly believe there are probably only 50 people on the planet who know how to scale these types of businesses efficiently in this era.
Always good to get that dose of SF. I felt sooo lucky to have such an incredible trip during such an incredible time in building businesses. Surreal in so many ways.
Happy to be home and locked in.
Until next time!


yonks|🤖🏛️🪙|Jason Younker retweeted

The number 1 complaint I hear from people is they just don't know wtf to do with AI agents
They set up Grok Bot, Muse, Hark, Dots, Hermes and then do nothing with it
So I'm launching a free project: Agent Use Cases
It's a website that scans the entire internet every day and finds every use case people do with AI agents
Searches across basically every site on the internet to see what people are doing with AI agents that is making them money/providing them value
Use cases are organized by category and which agent they're used in
Gives you the use case, end result, and prompt to steal the use case
Some cool use cases I've already discovered:
1. Finding unclaimed money online
2. Negotiate phone bill down autonomously
3. Teach an agent to day trade
It's completely free. Nothing pay walled. You can just go on and discover cool new use cases
I'd recommend browsing then giving the link of this post to your agent and having it find use cases relevant to you
Sign up for the newsletter if you want 5 new use cases in your inbox every morning too
Check it out: agentusecases.ai/

yonks|🤖🏛️🪙|Jason Younker retweeted

A 27B model shrinks from 54GB to 7.89GB,
that fits under 8GB and beats the full-size version at tool calling.
Saluki keeps 96% of Qwen 3.8 27B performance at roughly 1/7th the size and runs entirely on your Mac locally.

Today we're releasing Underdog Saluki 27B
Based on Qwen 3.8 27B, Saluki is almost 7x smaller than its full-precision counterpart while it keeps 96% of its benchmark performance and beats Qwen at tool calling
It's the best model <8GB that runs in Underdog
Saluki is available today under Apache 2.0. Try today in Underdog underdog.ai/saluki

yonks|🤖🏛️🪙|Jason Younker retweeted

The CFO job has gone from accountant to banker to builder, and the whole finance function is being rebuilt around it:
1. Data stopped being the bottleneck. AI pulls and reconciles data across systems, so teams spend more time acting on numbers instead of chasing them.
2. The finance stack is becoming part of the finance team. AI-native tools stand up in days, pull their own data, and turn a monthly close into a daily one.
3. The rise of the finance engineer. Finance people proficient in Claude Code or Codex are building their own tools.
4. The finance team gets smaller and higher leverage. The old heuristic of finance at 5% of headcount is heading to 2% for the leanest teams.
5. Planning becomes continuous. Usage-based revenue (tokens, API calls) moves too fast for a monthly forecast, so planning shifts from annual budgets to a live view.
6. Controls become a critical feature of the product. Every number an agent touches keeps an audit trail back to its source, and finance still owns sign-off.
7. Finance gets a bigger mandate. Compute spend, people versus software, and build versus buy are now finance decisions.
"The CFO is becoming a builder and architect of the company's operating system... The job is still finance, but more of the job now is designing how finance gets done."
a16z's @seemaamble, @IvanoMakSF, and David Borecky on why you need a new CFO: a16z.news/p/you-need-a-new-c…


🧵 [3/] Now the ARTIFACT
git.weown.tools/WeOwnSeason0…

yonks|🤖🏛️🪙|Jason Younker retweeted

Today I call upon the blockchain industry to calmly begin planning for "bunker mode". My personal recommendation is to set in motion a controlled mass migration of assets to fresh addresses, i.e. addresses whose pubkeys remain hidden behind a hash.
Holders, starting with large and sophisticated ones, should consider moving the bulk of their funds to addresses that have never signed a transaction. And when they do sign one, they should also move remaining funds to a new address (possibly generated from the same seed phrase).
Don't rush. While I believe there is cause for action a rushed migration would do more harm than good. Don't panic either. Moving assets to protected addresses is a simple, preventative step which does not require new cryptography or new wallets.
IMO it is now reasonable to brace for the possibility that ECDSA breaks before qday, in the worst case in months not years. By "break" I mean fast private key recovery (e.g. in one week) on available hardware (e.g. a large GPU cluster).
Recent days have been humbling for human mathematical intuition. Long-held, unquestioned hypotheses have fallen. This includes the n log(n) bound for integer multiplication and the 3SUM conjecture. In hindsight, May's unexpected disproof of the Erdős unit distance conjecture was our warning shot.
Yesterday's OpenAI drop made it clear that mathematical superintelligence is upon us. They say there are weeks where decades happen. We are about to live through weeks where centuries of mathematical progress happen. Could our magic 64-byte ECDSA signatures be too good to be true? Was it just security through obscurity all this time?
Elliptic curves feel especially vulnerable to superintelligence. Curves carry rich structure, with room for fancy tricks like Schoof, Frobenius, pairings. (By contrast, hashes are designed to minimise algebraic structure.)
Separately, as Ewin Tang can attest, an efficient quantum algorithm sometimes foreshadows an efficient classical one. We should be open to the possibility of a classical counterpart to Shor that breaks elliptic curves and RSA at once.
Also noteworthy is the striking under-representation of cryptographic breakthroughs among the 722 mathematical results OpenAI published. I've witnessed first-hand the US government censoring academic quantum cryptanalysis results. Backroom interventionism is my base case.
I urge large, sophisticated actors to lead by example. Project11's "risq list" (bitcoin-risq-list.projecteleven[.]com) is a great tracker of exposed BTC pubkeys. Binance, Bitbank, Robinhood, Bitfinex, and Tether have an opportunity to harden their cold storage. Next month I'll address institutions in London in a live Q&A (forum.ethereuminstitutional[.]org/london-2026).
Again, please do not rush. Wallets holding under 50 BTC enjoy partial cover from "Satoshi's shield", i.e. his 20K exposed addresses that hold 50 BTC each. Load-bearing signers like oracles and L2 security councils should consider rotating ECDSA pubkeys with every signed message and/or multi-signing with a hash-based schemes like SPHINCS.
Exiting bunker mode safely will require post-AI cryptography. My inclination is to go all-in on hash-based cryptography and avoid structured mathematical assumptions entirely, whether from curves, lattices, or isogenies. A single battle-tested hash (e.g. from the SHA or BLAKE families) yields plausible post-AI security.
The Ethereum roadmap on strawmap[.]org fully embraces hash-based cryptography with end-to-end formal verification as a response to the quantum threat. Those timelines must now be revisited and accelerated in light of mathematical superintelligence. I'll be pushing for maximum defensive acceleration.
yonks|🤖🏛️🪙|Jason Younker retweeted

The US government will give your startup up to $1.55M and take 0% equity.
@NSF's America's Seed Fund is open again after Congress reauthorized it in April.
Three tracks:
- Phase I: up to $305K to prove the idea
- Phase II: up to $1.25M to build it
- Fast-Track: up to $1.55M, both phases in one go
Who can apply:
- US-based startups with 500 or fewer employees
- 51%+ owned by US citizens or permanent residents
- Not majority owned by VCs
- All the work done in the US
How it works:
- Send a 3-page Project Pitch first
- NSF invites the best ones to submit a full proposal
- Next full proposal deadline: Nov 4
Phase I funding rates have run about 10 to 20%. It's work, but nobody takes your cap table.
Application link 👉 seedfund.nsf.gov
Bookmark and tag a tech founder who needs this.

yonks|🤖🏛️🪙|Jason Younker retweeted

As reported in the @WSJ, we have raised a Series B to bring Hermes Agent to new frontiers (and, yes, build a mobile app)
Thank you to our investors including @nvidia @M12vc @SamsungNext @robotventures @usv @ycombinator @MenloVentures, among others
wsj.com/pro/venture-capital/…


sharing my thoughts on our recent fundraise.
we did alright for a couple of goofballs
nousresearch.com/a-note-on-o…

yonks|🤖🏛️🪙|Jason Younker retweeted

🚨This is huge
Google has released EmbeddingGemma 2, a new open embedding model designed to run locally with just 0.5GB of RAM.


yonks|🤖🏛️🪙|Jason Younker retweeted
It finally happened
America has entered the frontier open weights model competition. We aren't rolling over to China
Reflection announced Beam, a 501B parameter open weights model that is comparable to GLM 5.2, Qwen 3.8, and Opus 4.8
Yes, Opus 4.8 on your desk
You will need a decent sized machine for this. Probably the Mac Studio 512gb
But if you listened to me back in January when I warned you days like today were going to come, then you're all set
I stand by Opus 4.5 being the most important model release in history. We will now have a model BETTER than that on our desks
If you haven't gotten into local AI yet, it's officially time to do it
Take any computer you have, talk to an AI agent, ask which models you can run
Never been more important to just start

Introducing Beam: a highly efficient agentic open model with 501B total parameters and 23B active.
- Frontier reasoning efficiency
- Advances the Western open frontier on coding & agentic tasks
- Trained end-to-end from scratch
Full weights release this month.
Learn more about Beam: reflection.ai/beam

yonks|🤖🏛️🪙|Jason Younker retweeted

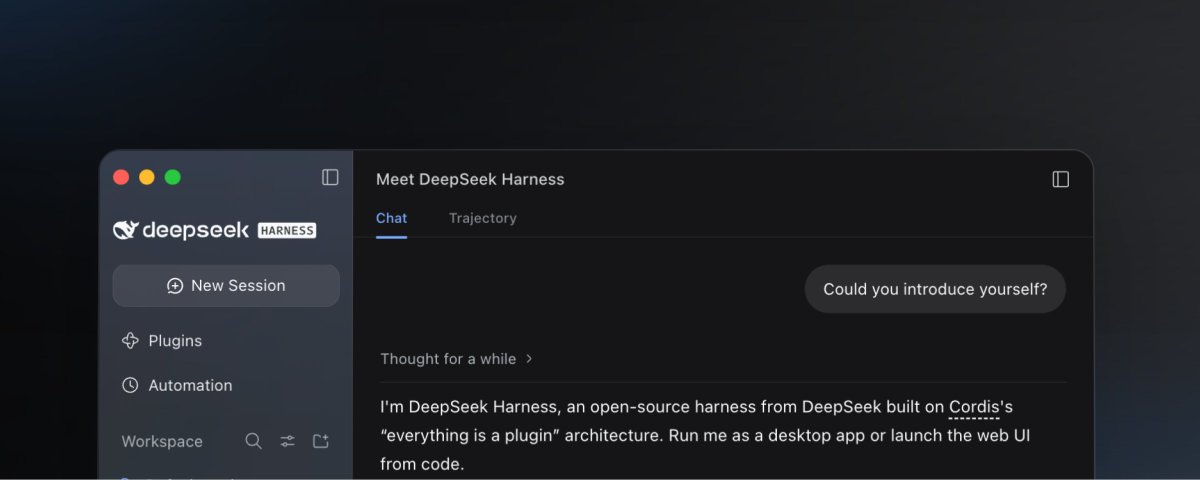
Please check out @DeepSeekHarness. We just released packaged desktop versions for macOS and Windows; Linux users can get it from the @deepseek-ai/dsh package on npm. deepseek.com/harness


yonks|🤖🏛️🪙|Jason Younker retweeted

Cloudflare's Clef beat Jev in just two weeks
How: "frozen" Qwen does one prefill pass, a tiny schema head scores every answer option in parallel, with no text generated at all.
That's why it's 4x faster than Jev at 2x the accuracy on some benchmarks.
And it's open source!
Link to HF:
huggingface.co/Cloudflare/cl…

yonks|🤖🏛️🪙|Jason Younker retweeted

Vice President JD Vance on H1-B visas:
"If you’re going to bring in an accountant making $45,000 a year to replace an accountant who is an American making $60,000 a year, that’s not you using the program to bring in a genius. That’s you destroying American jobs and defrauding the American people... my view is the H1-B program is completely broken."
yonks|🤖🏛️🪙|Jason Younker retweeted

Paste this into your favorite agent: "Connect to coinbase.com/skill.md"
Then follow the steps. Your agent can now see your portfolio, trade crypto, stocks, and derivatives, and pay for premium data with x402.
Try it out! (and let us know if you get stuck)

1) Document
2) Iterate
3) Automate
My #TLDR “Yonks Mantra”

Never automate a workflow on day one. Run it through 3 stages:
Stage 1: You run it by hand
Take one process, run it yourself (manually), review the required steps and the output. Do this a few times.
Stage 2: Someone else runs it
Your assistant runs the same manual process and sends you the result to approve. You're now checking outputs, not making them.
Stage 3: An agent runs it
The agent runs the process and drops the output in an approve/reject queue. You only see the queue.
The biggest mistake people make is jumping straight to stage 3 then trying to debug an automated process that was never optimized in the first place.
yonks|🤖🏛️🪙|Jason Younker retweeted

Never automate a workflow on day one. Run it through 3 stages:
Stage 1: You run it by hand
Take one process, run it yourself (manually), review the required steps and the output. Do this a few times.
Stage 2: Someone else runs it
Your assistant runs the same manual process and sends you the result to approve. You're now checking outputs, not making them.
Stage 3: An agent runs it
The agent runs the process and drops the output in an approve/reject queue. You only see the queue.
The biggest mistake people make is jumping straight to stage 3 then trying to debug an automated process that was never optimized in the first place.