

Building the platform for Continual Learning
Joined December 2025
- Tweets98
- Following1
- Followers5.2K
- Likes330
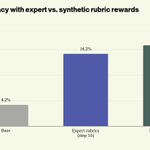




However, benchmarks are tidy and production isn’t, so these are just early results. But they show the direction we care about.
Base models turn over every few months, so what's durable is your tasks, your graders and your traces. With Trajectory, whoever owns that loop gets to swap in every new model the day it ships.

Huge thanks to @NVIDIAAI and @harvey . Nemotron keeps showing that open models can do real work, and they’re genuinely good to post-train on.
3.5 Super VL is live on Trajectory today. We’re really excited to see what customers do with it.
Read more: trajectory.ai/field-notes/ha…

Trajectory retweeted

7pm tonight @ 680 Folsom St, SF. @trajectorylabs x VESSL AI, for #sftechweek
RSVP: partiful.com/e/UdGWc3yV9ffPB…

Trajectory retweeted

NYC brought the energy to our latest Crusoe AI Talk! 🗽
Next stop 👉 tomorrow in SF: @ollama, @trajectorylabs, and Crusoe on the model decision (closed vs. open vs. proprietary).
Join us: luma.com/lnnlfa87
Everyone talks about the algorithms that train frontier models. What fewer people talk about is all the work it takes to make a model trainable in the first place.
Here's a look inside how we did it for GLM-5.3 and GLM-5.3 Flash

Finally, the trek itself: training both models on math with a tight 8K-token answer budget (as a way to induce difficulty).
After 20 steps on AIME:
GLM-5.3: 57% → 81%
Flash: 54% → 83%
And with that, we see the summit of the GLM mountain on the horizon.
And that’s the story! Along the way, we’ve upstreamed several OSS contributions that you can find in SkyRL.
If you’re interested in learning more, read the full write up here: trajectory.ai/field-notes/en…
Here's to many more expeditions 🧭

Trajectory retweeted

@trajectorylabs is at MIT’s career fair, come say hi!
Come solve an RL puzzle on off-policy correction, and you get a guaranteed interview :)

On @harvey's legal benchmark, the average number of tokens outputted dropped from 90k to 37k tokens (as compared to more standard RL), while retaining the same pass rate!
Same intelligence, but less yapping along the way.
We view our product as being the interface for continual learning, and with that, we think deeply about how every research breakthrough is just another intuitive interface on our product.
For intelligence density, we explored dials, routes, and token budgets. But, sometimes, the best interface, is no interface.
That's why every model on Trajectory is trained with intelligence density on by default.
Thanks to all of our partners, especially @Harvey and @Rogo, for building with us on the path to continual learning.
To do research at the frontier, we need to work with companies at the frontier, and we are so fortunate to be able to do so.
Read more at: trajectory.ai/field-notes/in…
There’s a good chance your open source model is costing more than the frontier.
Cheap tokens ≠ cheap tasks.
Here, we introduce Intelligence Density, and Density Aware Training, our post-training technique to achieve less wasted compute, better learning, all with no knobs to tune.
Enabled by default in every Trajectory model.