

AI inference optimization company that never charges you twice for cached tokens, making AI applications faster and dramatically cheaper to run anywhere.
Joined October 2025
- Tweets163
- Following24
- Followers360
- Likes74


𝟐 𝐝𝐚𝐲𝐬 𝐮𝐧𝐭𝐢𝐥 #𝐆𝐓𝐂𝐁𝐞𝐫𝐥𝐢𝐧! ⏳ Our Head of Engineering Nick Barcet presents 𝘛𝘦𝘯𝘴𝘰𝘳𝘮𝘦𝘴𝘩 𝘗𝘭𝘢𝘵𝘧𝘰𝘳𝘮 on @SUSE AI Factory with Nvidia. Oct 21, 3:30pm CEST, @SUSE Booth #3053. 𝐀𝐝𝐝 𝐢𝐭 𝐭𝐨 𝐲𝐨𝐮𝐫 𝐚𝐠𝐞𝐧𝐝𝐚!

We teamed up with @IBM, @nvidia and @Supermicro to test whether KV cache needs to live in RAM, using LMCache to tier context to IBM Storage Scale.
na2.hubs.ly/H08ryQX0

𝐒𝐭𝐨𝐩 𝐩𝐚𝐲𝐢𝐧𝐠 𝐭𝐨 𝐫𝐞𝐜𝐨𝐦𝐩𝐮𝐭𝐞 𝐭𝐡𝐞 𝐬𝐚𝐦𝐞 𝐜𝐨𝐧𝐭𝐞𝐱𝐭. ⚡ See how KV cache reuse cuts latency and GPU costs, live at #GTCBerlin. 𝐎𝐜𝐭 𝟐𝟏, 𝟑:𝟑𝟎𝐩𝐦 𝐂𝐄𝐒𝐓, @SUSE Booth #3053. #KVCache #AIInference

Today we’ve announced to the world that 𝐓𝐞𝐧𝐬𝐨𝐫𝐦𝐞𝐬𝐡 𝐏𝐥𝐚𝐭𝐟𝐨𝐫𝐦, the 𝐦𝐚𝐧𝐚𝐠𝐞𝐦𝐞𝐧𝐭 𝐥𝐚𝐲𝐞𝐫 𝐟𝐨𝐫 𝐀𝐈 𝐢𝐧𝐟𝐞𝐫𝐞𝐧𝐜𝐞 𝐝𝐚𝐭𝐚, is officially live and enterprise-ready 🚀
Read the full announcement 👇
na2.hubs.ly/H08nsMN0
We're heading to GTC Berlin! 🇩🇪 Join Tensormesh at @SUSE 𝐁𝐨𝐨𝐭𝐡 #𝟑𝟎𝟓𝟑 𝐨𝐧 𝐎𝐜𝐭 𝟐𝟏𝐬𝐭 𝐚𝐭 𝟑:𝟑𝟎𝐩𝐦 𝐂𝐄𝐒𝐓 for an intro to Tensormesh Platform on SUSE AI Factory with Nvidia. Reply if you'll be there!

𝑨𝑰 𝒄𝒐𝒔𝒕𝒔 𝒅𝒐𝒏'𝒕 𝒔𝒕𝒐𝒑 𝒂𝒕 𝒕𝒉𝒆 𝒕𝒐𝒌𝒆𝒏.
As models consume more tokens to tackle increasingly complex tasks, the compute, memory, storage, and energy behind them matter too.
AI economics and 𝒊𝒏𝒇𝒓𝒂𝒔𝒕𝒓𝒖𝒄𝒕𝒖𝒓𝒆 𝒆𝒇𝒇𝒊𝒄𝒊𝒆𝒏𝒄𝒚 are becoming the same conversation.
⬇️ na2.hubs.ly/H089px80

𝑲𝑽 𝒄𝒂𝒄𝒉𝒆 doesn't always disappear when a request is over.
For multi-turn, RAG, and agentic workloads, that state can end up in persistent storage. That raises another question: who has access?
𝑲𝒆𝒆𝒑𝒊𝒏𝒈 𝑲𝑽 𝒔𝒕𝒂𝒕𝒆 𝒂𝒓𝒐𝒖𝒏𝒅 𝒂𝒍𝒔𝒐 𝒎𝒆𝒂𝒏𝒔 𝒕𝒉𝒊𝒏𝒌𝒊𝒏𝒈 𝒂𝒃𝒐𝒖𝒕 𝒉𝒐𝒘 𝒊𝒕'𝒔 𝒑𝒓𝒐𝒕𝒆𝒄𝒕𝒆𝒅.
Your AI infrastructure doesn't need another rip-and-replace project.
Tensormesh Platform works across Kubernetes, accelerators, storage, and inference engines, so teams can build on the infrastructure they already have.
Explore the Platform. 👉na2.hubs.ly/H089pz-0
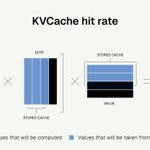
How much of your inference workload is 𝒂𝒄𝒕𝒖𝒂𝒍𝒍𝒚 new?
Tensormesh's #KVcache Hit Rate shows how often cached state is reused instead of recomputed, giving teams visibility into how much repeated work their models are doing.
You can't 𝑜𝑝𝑡𝑖𝑚𝑖𝑧𝑒 𝑟𝑒𝑝𝑒𝑎𝑡𝑒𝑑 𝑤𝑜𝑟𝑘 if you can't see it.

That's a wrap on #TheAIConference in SF! Thanks to everyone who stopped by to talk faster, more efficient AI inference. And yes, we met a robot. Say hi to Gerald! 🤖
#AIInfrastructure #KVCache @aiconference


Day 1 of The AI Conference SF is in the books! 🎉 Come say hi to the team at Booth #214. We're excited to show how Tensormesh Platform can speed up AI inference and cut GPU costs with intelligent KV caching. See you on Day 2!
#TheAIConference #AIInfrastructure #LLMInference #KVCache


SEE YOU THERE! We're at Booth #214 at T𝙏𝙝𝙚 𝘼𝙄 𝘾𝙤𝙣𝙛𝙚𝙧𝙚𝙣𝙘𝙚 2026, Sept 30 to Oct 1 at Pier 48 in San Francisco.
Come talk KV cache, GPU memory pressure, or anything else in your inference stack.
See you there.

Couldn't make our VAST Data webinar live? The recording's up.
"Demystifying KV Cache: Expert Advice on Architectures, Best Practices, and Sizing" with our CTO Yihua Cheng, now available to watch anytime.
🎥 na2.hubs.ly/H081jHD0

Panel prep mode: our CEO @JunchenJiang hits the HYSTA 2026 stage tomorrow for "From Compute to Scale," talking AI infra with folks from @OpenAI, @AMD, and @RadixArk.
na2.hubs.ly/H07TN4d0
#AI #HYSTA

A cache hit doesn't automatically mean an inference win.
The real question is whether reusing cached state is actually faster and more efficient than recomputing it.
Effective caching isn't just about storing more. It's about making reuse worth it.

Our trace analysis of RepoAgent is detailed via @BIS_Tweets: bisok.com/blog/how-cacheblen….

We're at Booth #214 at 𝗧𝗵𝗲 𝗔𝗜 𝗖𝗼𝗻𝗳𝗲𝗿𝗲𝗻𝗰𝗲 𝟮𝟬𝟮𝟲 next week, Sept 30 to Oct 1 at Pier 48 in San Francisco.
Come by if you want to talk through KV cache bottlenecks, GPU memory pressure, or anything else slowing down your inference stack. We'll have the team on hand and a few things worth seeing on the LMCache side.
📍 Booth #214
📅 Sept 30 to Oct 1
🏢 Pier 48, San Francisco
If you're going to be there, drop a comment. Happy to set up a time so we're not just waving from across the hall.

Tomorrow, 9AM PST: our CTO @YihuaCheng joins Vast Data's @AnatHeilper live on KV cache architecture, sizing, and best practices.
Moderated by @calvinnieh
na2.hubs.ly/H07V13C0
