
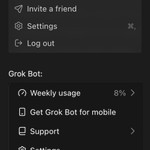




Codex measures the remaining
Grok measures the used
Same quota, opposite math. Why are we like this 😅


Tried out GPT Live,
Here are my thoughts: I see no difference they current voice models today, if anything I found it a little slower and sluggish. I only did try the trivia function.
I’ll go back in a few and try out the conversation function

OpenCode seems to have badly underestimated my Astra Pro usage.
OpenRouter ended up reporting roughly 3x the cost OpenCode showed me.
Has anyone else run into this? Is OpenCode miscalculating token usage/cost, or is there another reason for the gap?


@Tech retweeted

One DGX Spark on your desk is powerful. Four is a local AI factory.
NVIDIA DGX Spark now scales up to four clustered nodes, enabling inference on models up to 700B parameters — with near-linear performance scaling for fine-tuning and reinforcement learning workloads. Memory scales from 128GB on a single node all the way up for the full four-node configuration, supporting large context windows, high concurrency, and multi-agent workflows.
For APAC enterprise teams building autonomous AI: each topology is purpose-built for your workload — from rapid local iteration to production-scale inference. And when you're ready to move to the cloud, Tile IR and cuTile Python carry your kernels across with minimal code changes.
No rack. No rearchitecting. Just scale.
🔗nvda.ws/4w0RBPy
