

AI Cloud Blockchain | #DePIN #AI #Superchain #Cloud #EVM | Incubated by @protocollabs @BinanceLabs @OVioHQ @Optimism @chainlinklabs
Joined June 2021
- Tweets3K
- Following76
- Followers219K
- Likes1.6K




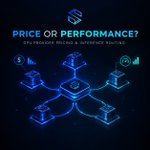


More models mean more choices. But how do users compare latency and pricing fairly?
Price per token is only one part of the equation.
→ Input/output cost
→ End-to-end latency
→ Throughput under load
→ Task success rate
A useful benchmark compares models under similar conditions and measures cost per successful task, not just the cheapest API or fastest response.
For decentralized inference, what matters most to you: price, latency, or reliability?

The cheapest GPU isn't necessarily the best GPU⏩
In decentralized inference, routing isn't just about finding the lowest price. It has to balance:
→ Cost per completed task
→ Model quality
→ Node uptime
→ End-to-end latency
Optimize only for price, and reliability or output quality may suffer.
Optimize only for quality, and inference costs can quickly spiral.
The real objective should be cost-efficient inference that meets performance and reliability targets.
How should decentralized networks balance these trade-offs when routing workloads?
🤖 Made with AI

New on Swan Inference 🧵
We just listed 5 models for roleplay & creative writing:
• MiMo V2.6 Flash RL (1M ctx)
• DeepSeek V4.1 Flash (1M ctx)
• Artemis 31B
• Skyfall 31B (TheDrummer)
• Qwen3.8 Queen 27B
Run a GPU? Serve them & earn 👇
github.com/swanchain/computi…

Raw token count hides the real bill once context and reasoning costs enter the picture. 🤔
A request with 2K output tokens doesn't necessarily cost the same as another 2K-token request.
Long context increases prefill compute.
Reasoning can add substantial inference compute.
KV-cache can reduce repeated computation while increasing GPU memory and bandwidth pressure.
Model architecture, batching, and GPU utilization further change the underlying compute profile.
For decentralized AI infrastructure, the real pricing question isn't simply:
- How many tokens were generated?
It's:
- How much compute and memory did the workload actually consume?
So what should AI infrastructure pricing actually measure: tokens, compute, or both?
-------
#SwanChain #AIInference #DePIN #DecentralizedAI
🤖 Made with AI

Live from #SolanaSummit today! 🚀
We’re connecting with the @solana ecosystem to explore the massive potential of decentralized computing.
We’re exploring what decentralized compute infrastructure could bring to Solana — and what new possibilities emerge when compute becomes more open, distributed, and accessible.⚡️
Early conversations, huge vision. Stay tuned! 🌐
------
#SwanChain #Solana #DecentralizedCompute #AI


🌐 The DePIN expansion is real.
The Swan 2.0 Decentralized AI Inference Marketplace is officially live and scaling globally!
We now have active independent GPU computing providers delivering real-time model serving from:
🇨🇦 Canada
🇳🇿 New Zealand
🇨🇿 Czechia
🇸🇰 Slovakia
🇨🇳 China
Low-latency, zero vendor lock-in, and full OpenAI-compatible API integration. Turn your idle GPUs into global AI infrastructure.
🛠️ Deploy or join the network today: inference.swanchain.io
🚀#SwanChain #DePIN #AI #Web3 #Crypto #GPU

Should GPU providers set their own prices?
On one hand, it makes sense.
Different GPUs, regions, power costs, utilization and infrastructure mean different operating economics.
But there’s a trade-off.
If routing optimizes primarily for price, do we risk sending workloads to the cheapest node rather than the best-performing one?
So what makes more sense for a decentralized inference marketplace:
- Uniform pricing?
- Provider-set pricing?
- Or pricing + performance-based routing?
What would you trust?
----
#SwanChain #AIInference #Inference #AIAgents #GenerativeAI
🤖 Made with AI

We’ve updated our pricing.
The old $6 Token Plan is now replaced by a simpler Prepaid Credits model:
• Any amount — list price
• $100+ — +2% credits
• $500+ — +4% credits
• $2,000+ — +6% credits
• Credits work across all models
No subscription. No model-specific plans. Just top up, use what you need, and keep the bonus.
inference.swanchain.io/prici…
🤖 Made with AI

🚀 SwanChain Computing Provider v0.6.0 is live!
Providers can now do much more directly from the node:
⚡ Serve / stop / manage models from the CLI
🧠 Estimate VRAM before loading a model
🔄 Plan & automate model switching
🤖 Use a local AI agent to manage the node
🔔 Get alerts whenever served models change
🛠️ Better multi-GPU support + dashboard fixes
From simply declaring models → to actually running, optimizing, and automating them.
Check out the release 👇
github.com/swanchain/computi…
🤖 Made with AI

Not all tokens are created equal in AI inference. 📊
When setting up AI subscriptions or pay-as-you-go pricing, relying purely on raw token quotas often hides a massive economic discrepancy: the underlying compute cost.
As shown in our breakdown:
🔹 Token volume ≠ Infrastructure expense: 1 million tokens generated via a large-parameter model consumes significantly more GPU compute, energy, and hardware bandwidth than 1 million tokens on a smaller, lightweight model.
🔹 The Routing Factor: Model routing choices and payout dynamics can drastically alter the true unit economics of an inference pipeline, creating huge cost gaps between power users and casual workloads.
This raises a critical question for AI infrastructure providers and developers: Should decentralized AI pricing be strictly quota-based, model-based, or compute-cost-based?
At Swan Chain, we are constantly optimizing our decentralized inference pipelines to deliver transparent, predictable, and sustainable pricing models that benefit both creators and computing resource providers.
What pricing model makes the most sense for your AI applications? Drop your thoughts below! 👇
#DecentralizedAI #AIInference #CloudComputing #ComputeEconomics #SwanChain #AIInfrastructure
🤖 Made with AI

Big news for Swan Chain inference providers and builders! 🚀
We’ve added DeepSeek models to the platform! 🎉 Whether you're running nodes to serve inference requests or building decentralized AI apps, you can now seamlessly call and supply DeepSeek endpoints.
🔗 Explore models & start building: inference.swanchain.io/netwo…
-----
#SwanChain #DeepSeek #AIInference

Should inference providers have a minimum payout guarantee?
Today, subscription traffic is paid from a shared pool. If usage exceeds subscription revenue, provider payouts are reduced proportionally.
That protects the protocol — but leaves providers carrying most of the demand risk.
If providers can't predict their yield, network stability suffers.
Would a minimum payout floor make decentralized inference more sustainable, or does it shift too much risk back to the network?
What's the right balance?
What’s your take on this? Share below!

🚀 Swan Inference Network is growing fast.
In the last 24 hours:
• 5,418 requests — ↑ 53.8%
• 48.7M tokens — ↑ 62.3%
• 6 providers online
• 26% network capacity utilized
More inference. More providers. More real workloads running on decentralized GPU infrastructure.
And we’re just getting started. 🦢
#SwanChain #AI #DePIN #GPU #Inference

🚀 The new Swan Chain Provider Console v0.5.2 is live!
Monitor requests, latency, earnings, model traffic, GPU health, and capacity—all from one dashboard.
github.com/swanchain/computi…
Put your GPUs to work with Swan Chain. inference.swanchain.io
#SwanChain #DePIN #AI #GPU

40M tokens doesn't mean 40M tokens of compute. 🔁
In decentralized inference, the real cost depends on more than token count:
→ Model selection
→ Input/output mix
→ Provider payout rates
→ Routing behavior
→ Hardware economics
Two users can consume the same token quota while creating very different costs for the network.
So should inference subscriptions be priced by tokens, models, or actual compute cost?
Curious how the Swan community would design it.? How would you design it? Drop your thoughts below!👇


