




Pinned Tweet
Today we release 𝚍𝟷-𝚞𝚕𝚝𝚛𝚊, our most powerful decision model.
> built for hard decision problems.
> d1-ultra is multimodal
> supports 44 languages
> #1 on the @ArtificialAnlys Decision Index (65)
> leads all eight categories of our 112-evaluation suite
1/

Liquid Context on @Qualcomm Snapdragon, can read, write and compress constant streams of data for agents to deliver value!
read more: liquid.ai/blog/liquid-contex…


Continuous sensing creates memory bottlenecks on edge devices. Qualcomm & @ramin_m_h, Co-founder and CEO of @LiquidAI are advancing on-device AI with Liquid Context on @Snapdragon — compressing multimodal inputs for fast, low-power execution.
Liquid AI retweeted

We released d1-ultra, the most capable decision model on the market! 🏆 It ranks #1 on the Artificial Analysis Decision Index by a wide margin.

Liquid AI retweeted

proud 🙏🏻

Building a model that fits on a phone or laptop makes pre-training harder. With fewer parameters, quality has to come from better architecture and better data, not just more compute. Our pre-training team, including @TadimetiAditya and @Khoi_H_Nguyen, explains how they design LFMs with the target device in mind from day one.
Building a model that fits on a phone or laptop makes pre-training harder. With fewer parameters, quality has to come from better architecture and better data, not just more compute. Our pre-training team, including @TadimetiAditya and @Khoi_H_Nguyen, explains how they design LFMs with the target device in mind from day one.


Liquid AI retweeted

I wanted to see how well decision models are at... Finding Waldo.
After 66 scenes, here are the results:
- @liquidai d1-ultra found the most Waldos
- @typesafeai Jev 1.14 was the quickest
-@perplexity_ai Decider Flash V1.2 was the cheapest
waldobench.gao.haus

Liquid AI retweeted
aaand Liquid d1 for @huggingface robot control 🤖

Liquid's d1-3B picks a skill like walk, turn, pick, sit.
A trained policy does the move on Microduck.
157 ms, on an Intel Arc b580
Decision models can also be used for robotics*
@liquidai @pollenrobotics
Liquid AI retweeted

Liquid's d1-3B picks a skill like walk, turn, pick, sit.
A trained policy does the move on Microduck.
157 ms, on an Intel Arc b580
Decision models can also be used for robotics*
@liquidai @pollenrobotics
Liquid AI retweeted
damn! actual “decision tree” with Liquid d1 🌱🌱🌱🌱🌱🌱🌱🌱🌱🌱🌱🌱🌱🌱🌱

Actual “decision tree”.
@Raspberry_Pi 5 running @liquidai d1 600m
Being powered by solar
With a diy tree connected to
Figuring out how to productize this for < $125

Liquid AI retweeted

Actual “decision tree”.
@Raspberry_Pi 5 running @liquidai d1 600m
Being powered by solar
With a diy tree connected to
Figuring out how to productize this for < $125
Liquid AI retweeted

I added @liquidai’s d1-3B decision model to my hacked TV so I can talk to it
Inspired by @doooyle, I hacked my TV with Claude Code and cleaned up all the bloatware. But I realized I hate using the TV OS.
I wanted my TV to be content-first, not apps-first. So I wired a decision model in between that opens the right app and sends the right ADB commands based on my intent.

Hacked my TV with Claude Code today
No more ads, bloatware, spyware or laggy UI
I also got a beautiful screensaver with my revenue, calendar, weather, and notifications for new Stripe payments
It was super easy! I sent it the listing for my tv, asked "can you hack this?" And it talked me through how

Liquid AI retweeted

Jev dethroned!!!

Liquid AI has released d1-ultra, taking the #1 position on the Artificial Analysis Decision Index v1.0, supported by a reduction in hallucinations
d1-ultra is the new decision model from @liquidai and follows on from their release of d1 earlier this month. It is priced at $0.042 per 1M input tokens compared to $0.02 per 1M input tokens for d1. Like d1, d1-ultra is billed only on input tokens.
Key takeaways:
➤ d1-ultra leads the Artificial Analysis Decision Index v1.0 with a score of 65: d1-ultra scores 65, ahead of the recently released Jev 1.14 at 57 and GLiDE and Microsoft-Decision-1 at 54
➤ d1-ultra’s score of 65 is driven by a much lower hallucination rate on AA-Omniscience-Decision: d1-ultra’s non-hallucination rate on AA-Omniscience-Decision is 85%, up substantially compared to d1 at 2%. The non-hallucination rate is the share of questions not answered correctly where the model chose "I don't know" and measures how well a decision model can judge its own knowledge in knowing when not to answer. While d1-ultra’s hallucination rate decreases, so does its accuracy (% questions correct). It achieves an accuracy of 32%, down 9 points compared to d1 (41%)
➤ d1-ultra has the third lowest Time per Task of any decision model: d1-ultra achieves a Time per Task of 92 ms, the third lowest of decision models measured, behind Jev 1.14 at 78 ms per task and Celeris-1 Decision at 63 ms per task
➤ d1-ultra offers comparable pricing to other decision models at $32 per 1M tasks: At $32 per 1M tasks, d1-ultra is comparably priced to Celeris-1 Decision ($32 per 1M tasks) and Microsoft-Decision-1 ($31 per 1M tasks), more than double the price of d1 and Mercury Decide at $15 per 1M tasks but less than half the price of GPT-6 Luna (Decisions) at $79 per 1M tasks

Liquid AI retweeted

Liquid AI just released a model that claims the top spot on a dedicated Decision Index and leads all eight categories in their own 112-evaluation suite.
Most AI releases are still judged on general benchmarks (coding, math, knowledge). Decision models are optimized for something narrower: choosing among fixed options under constraints, often with multimodal inputs. That is closer to how a lot of enterprise work actually happens (approvals, prioritization, routing, risk scoring) than open-ended chat.
If the benchmark results hold up outside their suite, this is another signal that the market is splitting. General models keep getting more capable. Specialized models are starting to win on the narrower jobs where companies are willing to pay for reliability over flexibility. The companies that figure out which workflows belong in each bucket will get better unit economics than the ones still forcing everything through a single frontier model.
Today we release 𝚍𝟷-𝚞𝚕𝚝𝚛𝚊, our most powerful decision model.
> built for hard decision problems.
> d1-ultra is multimodal
> supports 44 languages
> #1 on the @ArtificialAnlys Decision Index (65)
> leads all eight categories of our 112-evaluation suite
1/
Liquid AI retweeted

#Liquid has released d1-ultra, a new multimodal (text, images, or both) decision model with state-of-the-art performance.
It can answer questions about a situation and assign a probability to each possible answer for unstructured input data: liquid.ai/blog/d1-ultra

Liquid AI retweeted

oh hi 👋
Liquid AI has released d1-ultra, taking the #1 position on the Artificial Analysis Decision Index v1.0, supported by a reduction in hallucinations
d1-ultra is the new decision model from @liquidai and follows on from their release of d1 earlier this month. It is priced at $0.042 per 1M input tokens compared to $0.02 per 1M input tokens for d1. Like d1, d1-ultra is billed only on input tokens.
Key takeaways:
➤ d1-ultra leads the Artificial Analysis Decision Index v1.0 with a score of 65: d1-ultra scores 65, ahead of the recently released Jev 1.14 at 57 and GLiDE and Microsoft-Decision-1 at 54
➤ d1-ultra’s score of 65 is driven by a much lower hallucination rate on AA-Omniscience-Decision: d1-ultra’s non-hallucination rate on AA-Omniscience-Decision is 85%, up substantially compared to d1 at 2%. The non-hallucination rate is the share of questions not answered correctly where the model chose "I don't know" and measures how well a decision model can judge its own knowledge in knowing when not to answer. While d1-ultra’s hallucination rate decreases, so does its accuracy (% questions correct). It achieves an accuracy of 32%, down 9 points compared to d1 (41%)
➤ d1-ultra has the third lowest Time per Task of any decision model: d1-ultra achieves a Time per Task of 92 ms, the third lowest of decision models measured, behind Jev 1.14 at 78 ms per task and Celeris-1 Decision at 63 ms per task
➤ d1-ultra offers comparable pricing to other decision models at $32 per 1M tasks: At $32 per 1M tasks, d1-ultra is comparably priced to Celeris-1 Decision ($32 per 1M tasks) and Microsoft-Decision-1 ($31 per 1M tasks), more than double the price of d1 and Mercury Decide at $15 per 1M tasks but less than half the price of GPT-6 Luna (Decisions) at $79 per 1M tasks
Liquid AI retweeted

Fine-tune and run your Jev at home on your MacMini 👇

how do you fine-tune a decision model on your own data?
in these two notebooks, you'll learn:
• how to prepare the training data
• how to fine-tune our d1-3B decision model
• using @UnslothAI and @huggingface TRL
all within 30 minutes on a free-tier GPU.
unsloth: github.com/Liquid4All/cookbo…
TRL: github.com/Liquid4All/cookbo…
ps: how adorable are these halloween kitties? 👻

Liquid AI retweeted

I've built an incredible todo system with @liquidai
D1-3B for action routing (e.g. create new or edit existing)
LFM-2.5-24B-A2B for synthesizing transcription blobs into titles, descriptions, and deadlines
LFM-2.5-Embedding-350M for semantic lookups
Local AI at its best.
Liquid AI retweeted

This is the craziest model ever! 👏🤗
Today we release 𝚍𝟷-𝚞𝚕𝚝𝚛𝚊, our most powerful decision model.
> built for hard decision problems.
> d1-ultra is multimodal
> supports 44 languages
> #1 on the @ArtificialAnlys Decision Index (65)
> leads all eight categories of our 112-evaluation suite
1/
Liquid AI retweeted

Liquid AI's d1-ultra just took #1 on the Artificial Analysis Decision Index. Here's what you need to know.
This is new since TypeSafe's Jev news. Liquid AI released d1-ultra, its most powerful decision model, following d1 earlier this month. Artificial Analysis scored it 65 on its Decision Index v1.0. That is ahead of Jev 1.14 at 57, plus GLiDE and Microsoft-Decision-1 at 54. Jev 1.13 scored 58.
Like Jev, it doesn't write text. It returns calibrated probabilities over outcomes you define. It is multimodal, takes text and images, and supports 44 languages. Liquid says it fits agentic orchestration, routing, guardrails, content moderation, fraud screening, document intake, search ranking and robot control.
The score comes from fewer hallucinations. On AA-Omniscience-Decision, the non-hallucination rate is the share of wrong-or-unknown questions where the model said "I don't know". d1-ultra hits 85%, up from 2% for d1. The next best model is at 40%. But accuracy fell from 41% to 32%. Saying "I don't know" has a cost.
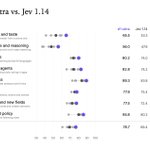
Liquid's own 112-evaluation suite shows d1-ultra leading all eight categories. It averages 76.7 against 69.4 for Jev 1.14. An independent test on 2,408 Games2p2k situations was close. Average error was 10.9 points for d1-ultra and 11.8 for Jev. Jev won on calibration.
Key numbers:
- Price: $0.042 per 1M input tokens, up from $0.02 for d1
- Billing: input tokens only, no output tokens
- Speed: 93 ms per task
- Cost: $32 per 1M tasks, close to Celeris-1 Decision at $32 and Microsoft-Decision-1 at $31
- Access: API only, no open weights, also on OpenRouter
Some users are upset that Liquid kept this model closed.

Liquid AI has released d1-ultra, taking the #1 position on the Artificial Analysis Decision Index v1.0, supported by a reduction in hallucinations
d1-ultra is the new decision model from @liquidai and follows on from their release of d1 earlier this month. It is priced at $0.042 per 1M input tokens compared to $0.02 per 1M input tokens for d1. Like d1, d1-ultra is billed only on input tokens.
Key takeaways:
➤ d1-ultra leads the Artificial Analysis Decision Index v1.0 with a score of 65: d1-ultra scores 65, ahead of the recently released Jev 1.14 at 57 and GLiDE and Microsoft-Decision-1 at 54
➤ d1-ultra’s score of 65 is driven by a much lower hallucination rate on AA-Omniscience-Decision: d1-ultra’s non-hallucination rate on AA-Omniscience-Decision is 85%, up substantially compared to d1 at 2%. The non-hallucination rate is the share of questions not answered correctly where the model chose "I don't know" and measures how well a decision model can judge its own knowledge in knowing when not to answer. While d1-ultra’s hallucination rate decreases, so does its accuracy (% questions correct). It achieves an accuracy of 32%, down 9 points compared to d1 (41%)
➤ d1-ultra has the third lowest Time per Task of any decision model: d1-ultra achieves a Time per Task of 92 ms, the third lowest of decision models measured, behind Jev 1.14 at 78 ms per task and Celeris-1 Decision at 63 ms per task
➤ d1-ultra offers comparable pricing to other decision models at $32 per 1M tasks: At $32 per 1M tasks, d1-ultra is comparably priced to Celeris-1 Decision ($32 per 1M tasks) and Microsoft-Decision-1 ($31 per 1M tasks), more than double the price of d1 and Mercury Decide at $15 per 1M tasks but less than half the price of GPT-6 Luna (Decisions) at $79 per 1M tasks