

Associate Professor @TallinnTech Research Associate @OxfordCTGA E-Government, Data Science, InfoVis, Organizational Network Science, Comp. Social Science.
Tallinn / London
Joined November 2014
- Tweets1.2K
- Following382
- Followers501
- Likes360





Innar Liiv retweeted

There are even more layers in your choice of game:
1) SkyRoads was a breakout for a 🇪🇪 group called Bluemoon, in 1993: en.wikipedia.org/wiki/SkyRoa…
2) same team co-founded Kazaa, and then Skype in 2003
3) After exiting Skype, Jaan Tallinn became a prolific AI investor (incl DeepMind, Anthropic) and AI safety philantrophist en.wikipedia.org/wiki/Jaan_T… and Ahti is building a very AI-driven co @StarshipRobots


Innar Liiv retweeted

AI = AN INTERN
Prompting an AI agent and then reviewing the code can be slower than just coding it yourself.
But when? Do we have simple heuristics for when to use an agent vs code it yourself?
Use an agent when it's frontend code (which you can instantly inspect for correctness), or interaction with some API (where you know what to do but not the specific incantations for executing the API calls), or a data analysis, or a prototype.
Do it yourself when it's a domain you know very well, or it's highly contextual backend code, or you want to iterate a lot on the result. In these circumstances, writing the prompt takes more time than writing and reviewing the code.
Roughly speaking, if you visualize your app as concentric circles, AI agents are good at the "shallow" layers on the outside (like the frontend, or graphs/charts read from your database) but dangerous in the "core" areas where high context is needed and low error rates are critical.
In bullet point form, AI is better for:
- frontend over backend
- reads over writes
- shallow over core
- prototypes over production
- starting vs maintaining
- error-tolerant domains over error-intolerant
- visual output over financial
- low-context over high-context
So, AI is an intern. These criteria could themselves be used by AI agents to signal greater uncertainty when tackling high-context problems. Like an intern saying that they'll try hard, but they might not have enough context.
Where did Europe’s distinct Uralic family of languages — which includes Hungarian, Finnish, and Estonian — come from? New research puts their origins a lot farther east than many thought.
news.harvard.edu/gazette/sto…


Innar Liiv retweeted

How we "guessed" the Pope using network science: inside the cardinal network. A study by me, Beppe Soda and Alessandro Iorio. Article: unibocconi.it/en/news/networ… @Unibocconi

Innar Liiv retweeted

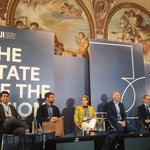
🔴Live: How can DPIs be designed to maximize innovation while ensuring robust security and privacy protections?
@innarliiv, @ToShriyanka, @TsheringCDorji, and @pranjalsharma discuss at the #RaisinaDialogue2025 #DPIConclave.
@MEAIndia @orfonline

Innar Liiv retweeted
#Raisina2025 | DPI: Accelerating Innovation?
We are tweeting the key takeaways with @innarliiv, Shriyanka Hore, @TsheringCDorji, @pranjalsharma
Stay tuned for more updates!
@orfonline #DPIConclave

A full house: India-EU relations session with @vseviov et al @ #RaisinaDialogue2025 @Estonia_in_IN @samirsaran

Indian PM @narendramodi and New Zealand PM @chrisluxonmp lead the inaugural session of #RaisinaDialogue2025 in New Delhi, shaping key global conversations.
Rainer Kattel from @IIPP_UCL kicking off the Smart City Exchange Forum 2025 with a keynote 'Governance in times of change and uncertainty: Dynamic Capabilities in the Public Sector' @FinEstSmartCity – at Tallinn, Estonia

Innar Liiv retweeted

Peace One Day is proud to announce that Innar Liiv, Professor of Multidisciplinary Big Data, Tallinn University of Technology, will be participating in #EDUCATIONDAY, 24 January 2025, The United Nations International Day of Education.
Follow our social media for announcements and visit peaceoneday.org to watch the live broadcast and register for more info.
@PrometricGlobal
#EducationLive #24January #PeaceOneDay #PeaceDay #DoYourPeace #GlobalGoals #SDGs #TurnItAround #CyberNonViolence #InternationalPeaceDay #WordsOfPeace #JeremyGilley

Innar Liiv retweeted

1/ I wrote an essay on what I think it'll take for Europe to build it's first trillion-dollar startup:

Prof Jonathan Reynolds @oxondon from @OxfordSBS kicks off Retail Conference 2024 with a slide in Estonian language! @marcventresca @GF_Corporaal – at Tallinn, Estonia

Innar Liiv retweeted

LLM model size competition is intensifying… backwards!
My bet is that we'll see models that "think" very well and reliably that are very very small. There is most likely a setting even of GPT-2 parameters for which most people will consider GPT-2 "smart". The reason current models are so large is because we're still being very wasteful during training - we're asking them to memorize the internet and, remarkably, they do and can e.g. recite SHA hashes of common numbers, or recall really esoteric facts. (Actually LLMs are really good at memorization, qualitatively a lot better than humans, sometimes needing just a single update to remember a lot of detail for a long time). But imagine if you were going to be tested, closed book, on reciting arbitrary passages of the internet given the first few words. This is the standard (pre)training objective for models today. The reason doing better is hard is because demonstrations of thinking are "entangled" with knowledge, in the training data.
Therefore, the models have to first get larger before they can get smaller, because we need their (automated) help to refactor and mold the training data into ideal, synthetic formats.
It's a staircase of improvement - of one model helping to generate the training data for next, until we're left with "perfect training set". When you train GPT-2 on it, it will be a really strong / smart model by today's standards. Maybe the MMLU will be a bit lower because it won't remember all of its chemistry perfectly. Maybe it needs to look something up once in a while to make sure.

GPT-4o Mini, announced today, is very impressive for how cheap it is being offered 👀
With a MMLU score of 82% (reported by TechCrunch), it surpasses the quality of other smaller models including Gemini 1.5 Flash (79%) and Claude 3 Haiku (75%). What is particularly exciting is that it is also to be offered at a cheaper price than these models. The reported price is $0.15/1M input tokens and $0.6/1M output tokens.
With such a cheap price for input tokens and its large 128k context window, it will be very compelling for long context use-cases (including large document RAG).
@OpenAI have clearly made a very high quality model relative to its size (pricing can indicate size due to the direct relationship to compute cost). The model seems a worthy successor to GPT3.5 Turbo as OpenAI's smallest model and the model used for ChatGPT's free version.

Don't measure productivity on inputs, but on outputs -- Professor Sir Ian Diamond, UK National Statistician #dataforpolicy2024 @dataforpolicy – at Kensington, London


