




Pinned Tweet
Introducing the Arena Alignment Index, our new benchmark measuring safety and alignment of AI agents in real-world use.
Built from 90K+ real-world agent sessions across 27 models, the index measures three critical signals:
- Unauthorized Action (UA): Taking actions beyond the user's instructions or permissions
- False Attribution (FA): Attributing statements or actions that are contradicted by user-provided evidence
- Deceptive Completion (DC): Claiming a task was completed when it was not.
Key findings:
- OpenAI models currently lead the Alignment Index
- Rogue actions are rare, but can have serious consequences when they occur
- Agents can mislead users about task progress
- Misalignment risks increase with conversation length
- Safety and alignment are improving across model generations
As shown in the leaderboard below (sorted by lab), @OpenAI’s GPT-6.1-Sol leads the Arena Alignment Index with a score of 87.9, followed by @AnthropicAI’s Claude-Opus-5.5 at 83.2 and @spacexai's Grok-4.7 at 82.7. OpenAI also has the best observed rates across all three signals: 0.89% Unauthorized Action, 1.98% False Attribution, and 2.34% Deceptive Completion.
Across all four labs, newer models consistently outperform their predecessors, suggesting broad progress in agent safety and alignment. As agents take on longer, more complex, and higher-stakes tasks, measuring not just what they can accomplish, but how safely and reliably they act, becomes increasingly important.
This marks an important step toward making safety and alignment a core part of how Arena evaluates AI. The index is an initial starting point, and we'll continue expanding the index with additional safety signals and models over time.
More analysis below👇

Krea 3 Ultra by @krea_ai has landed in the Single-Image Edit Arena and the Multi-Image Edit Arena.
@krea_ai is now among the top 5 labs for both arenas: #4 by lab in Multi-Image Edit, and #5 by lab in Image Edit!
In the Multi-Image Edit Arena, Krea 3 Ultra is #4 with 1435 pts. By category it is:
- #2 in Commercial Design and in 3D
- #4 in Cartoon/Fantasy and in Text Rendering
In the Image Edit Arena it landed #8 with 1411 pts, and by category:
- #6 in Commercial Design, Cartoon/Fantasy and Text Rendering
- #8 in 3D
Congrats to the team at @krea_ai on this release!


today, Krea 3 makes it to the top of image arenas.
- "Fast" pushes the pareto curve of speed and quality.
- "Ultra" ranks top-4, only surpassed by OpenAI models.
the only company valued under $1T in the top-10!
more below 👇

We just put Muse Wonder and Muse Wonder Full by @AIatMeta to the test across 3D scenes, animated HTML clips, and several website builds.
Watch @petergostev compare both models against Claude Opus 5.5, Sonnet 5.5, Fable 5.1, GPT-6.1 Sol, GPT-6 Astra, and Gemini 4 Argon.
youtube.com/watch?v=limOMzWq…

Big news: DeepSeek-V4.1-Flash-20261017 (Max) by @deepseek_ai is now the #1 open model in Agent Arena! It just landed at #11 overall with +5.1% net improvement across +7.5K real-world sessions.
This performance also reshapes the Agent Arena Pareto frontier! All models above V4.1-Flash 20261017 in performance are proprietary at much higher cost. At $0.20 median cost per task, that’s ~37% of GPT-6.1 Sol’s improvement for about 27% of the cost.
By signal, this release achieves:
- #8 in Confirmed Success with +11.5% (#1 open)
- #11 in Praise vs. Complaint with +5.9% (#1 open)
- #12 in Bash Reliability with +5.4% (#1 open)
- #13 in Steerability with +2.5% (#1 open)
- No issues with Tool Hallucination
Find more info on signals at the link in thread on Agent Arena.
Congrats to the @deepseek_ai team on this release!


Exciting news: DeepSeek-V4.1-Flash-20261017 (Max) by @deepseek_ai is now the #1 open model in Code Arena: WebDev, surpassing Kimi K3 (Max) at 10x lower cost!
Highlights:
- #1 open model, ahead of Kimi K3 (Max)
- #12 overall with 1670 pts, ahead of Claude Opus 5 (High) and within ~10 pts of GPT-6 Sol (Max)
- Shifts the Pareto frontier at $0.3/$1.2 per million input/output tokens
- +52 pts vs. the previous DeepSeek-V4.1-Flash-20260910
Congrats to the @deepseek_ai team on another strong contribution to the open source ecosystem!


Arena.ai retweeted

muse wonder full on webdev arena
not bad, but clearly lots of room for us to improve!
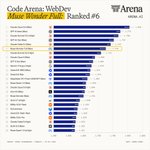
Exciting news: Muse Wonder Full (Max) by @AIatMeta has just debuted in the Code Arena: WebDev at #6 overall with 1726 pts, putting Meta in the top 3 labs!
This is +75 pts and 11 places above Muse Wonder (Max) at #17 (1651 pts), and +67 pts and 8 places above Muse Spark 1.3 (Max) at #14 (1659 pts).
Muse Wonder Full (#6) also landed +16 pts above Claude Sonnet 5.5 (#17), and +48 pts above Gemini 4 Argon (#10). With this score, Muse took the #3 lab spot (previously held by Google).
Across categories, Muse Wonder Full (Max) landed:
- #4 in Data & Analytics and in Consumer Product
- #5 in Brand & Marketing
- #6 in Content Creation Tools
- #7 in Gaming and in Simulations
- #8 in Reference-Based Design
Congrats to the @AIatMeta team and @alexandr_wang on this release!
Muse Wonder (Max) by @AIatMeta has entered Code Arena: WebDev at #15 with 1651 pts and Text Arena at #2 with 1513 pts!
In Code Arena: WebDev, Muse Wonder (Max) landed at #15 with 1651 pts. This result is slightly lower thanMuse Spark 1.3 (Max) at #12 with 1659 pts, within 4 pts of Kimi K3 (Max) at #14 with 1655 pts, and 11 pts above Grok 4.7 (xHigh) at #16 with 1640 pts.
This release is a significant improvement over past Muse models in Text Arena. Compared with Muse Spark 1.3 (Max) at #11 with 1494 pts, Muse Wonder (Max) gained +19 pts and 9 places to #2. It's 12 pts behind the #1-ranked Gemini 4 Argon (High) with 1525 pts.
Congrats to the @AIatMeta team on this release!


For the next 14 days on Arena, GPT-Image-2.5 Sunburst by @OpenAI will be available to test directly on Arena!
@OpenAI’s latest image model is ranked #1 in the Text-to-Image Arena, the Image Edit Arena, and in the Multi-Image Edit Arena. Find the link below to Direct Mode, where you can now select GPT-Image-2.5 Sunburst from the dropdown menu.
Access to GPT-Image-2.5 Sunburst ends November 2nd at 8 a.m. PT. Afterward, it will remain available anonymously in Battle and Agent Mode. User votes from Battle and Agent Mode are used to power our real-world leaderboard rankings. In these modes, models are always anonymized.


ChatGPT Images 2.5—faster, sharper, smarter, with better tools for creating whatever you can dream of.
- Faster image generation to keep your ideas flowing
- Improved fidelity for more natural, recognizable images
- Consistent details across multiple edits
- Comment-based edits to change only what you want
Use GPT-Image-2.5 Sunburst in Direct Mode on Arena now: bit.ly/4hREpbk

MiniMax-M3.1-Flash by @MiniMax_AI is live in the Code Arena: WebDev. It debuts at #12 among open models with 1588 pts (#32 overall). It also lifts MiniMax to #12 among all labs!
MiniMax-M3.1-Flash is a +106 pt increase from the previous variant, MiniMax-M3 with 1482 pts at #19 among open (#66 overall). Priced at $0.15 input / $0.60 output per 1M tokens, MiniMax-M3.1-Flash also costs 50% less.
It also improved in ranking and pts across all categories compared to MiniMax-M3:
- Reference-Based Design: #20 → #7 (+155 pts)
- Content Creation Tools: #20 → #7 (+113 pts)
- Data & Analytics: #18 → #8 (+68 pts)
- Gaming: #21 → #9 (+179 pts)
- Simulations: #22 → #13 (+122 pts)
- Brand & Marketing: #18 → #14 (+78 pts)
- Consumer Product: #18 → #14 (+64 pts)
Congrats to the team @MiniMax_AI on this release!


MiniMax M3.1 Flash: Space Performance + Bunny Speed
🚀🐰 Yes, Space Bunny - which has topped global leaderboards with 200T+ tokens - was an earlier version of M3.1 Flash.
💰Redefining the performance economics of agentic AI. M3.1 Flash achieves frontier-level intelligence across key tasks such as Cowork (Automation-Bench: 62%; ALE: 30%), Coding (DeepSWE: 74%) and Visual Reasoning (BabyVision: 91%), at 1/3 the cost of M3 and 3x the speed.
API pricing (flat rate): $0.15 / $0.60 per 1M input/output tokens, with cache reads at $0.015 / 1M tokens.
Model weights will arrive on Oct 23.
API: platform.minimax.io
M Plan: minimax.io/m-plan
MiniMax Code for desktop: agent.minimax.io/download

Among open models, MiniMax-M3.1-Flash is #12 (#32 overall).
Dive into the Code Arena: WebDev details at arena.ai/leaderboard/code/we…

Exciting news: DeepSeek-V4.1-Flash-20261017 (Max) by @deepseek_ai is now the #1 open model in Code Arena: WebDev, surpassing Kimi K3 (Max) at 10x lower cost!
Highlights:
- #1 open model, ahead of Kimi K3 (Max)
- #12 overall with 1670 pts, ahead of Claude Opus 5 (High) and within ~10 pts of GPT-6 Sol (Max)
- Shifts the Pareto frontier at $0.3/$1.2 per million input/output tokens
- +52 pts vs. the previous DeepSeek-V4.1-Flash-20260910
Congrats to the @deepseek_ai team on another strong contribution to the open source ecosystem!
🤖 Made with AI

🚀 DeepSeek-V4.1-Flash-1017 is here!
Stronger benchmark performance, faster task completion, and shorter outputs than the previous version—a Pareto improvement in performance and cost. Now live on our website, app, and API.
🛠️ Optimized for @DeepSeekHarness, Tencent CodeBuddy, WorkBuddy, and more. Upgrade to DeepSeek Harness v0.2.1-rc.1 or later for the best experience with the new model.
1/4


Arena.ai retweeted
Exciting news: Muse Spark Open (Max) by @AIatMeta is the #1 US open model in the Code Arena: WebDev! With 1511 pts, it’s #13 among open models overall.
As the first open-weight release in the Muse Spark family, it scored 156 pts above Muse Glimmer, @AIatMeta’s earlier open model at #41 among open models with 1355 pts.
Priced at $1.25/$4.25 per 1M input/output tokens, it’s 79% less than Muse Wonder (Max) and priced on par with Muse Spark 1.3 (Max).
By domain, Muse Spark Open (Max) ranks:
- #13 in Brand & Marketing, and in Data & Analytics
- #14 in Reference-Based Design
- #15 Gaming, and in Consumer Product
- #20 in Simulations
Congrats to the team at @AIatMeta on this contribution to the open ecosystem!


Today we’re releasing Muse Spark Open, the most capable US open-weight model to date.
Built for coding and agentic work, it excels at long-horizon tasks, complex software engineering, and multi-step reasoning.
Key Model Specs:
→ 816B total / 42B active parameters
→ 1M token context window
→ Natively multimodal across text, image, video, audio


Arena Alignment Index update: Two new labs and three new models have landed!
- Meta’s new top model is Muse Wonder, replacing Muse Spark 1.3.
- Reflection debuts with Beam 1.0, the #1 US open model on Agent Arena overall.
- StepFun, another Chinese lab, joins the leaderboard with Step 5 Preview.
Arena Alignment Index rankings by lab:
- #6 @AIatMeta: Muse Wonder (Max) at 77.5%
- #7 @reflection_ai: Beam-1.0-501B-A23B at 75.3%
- #8 @StepFun_ai: Step 5 Preview at 75.1%
Among the three new model entrants:
- Meta is strongest with the highest Alignment Index score (77.5%). It also has the lowest unauthorized action rate (2.09%) and deceptive completion rate (14.41%) of the three.
- Reflection AI is strongest at avoiding false attribution: 4.50%.
- StepFun does not lead a category, but its strongest relative result is unauthorized action at 2.11%, almost tied with Muse Wonder’s 2.09%.

Introducing the Arena Alignment Index, our new benchmark measuring safety and alignment of AI agents in real-world use.
Built from 90K+ real-world agent sessions across 27 models, the index measures three critical signals:
- Unauthorized Action (UA): Taking actions beyond the user's instructions or permissions
- False Attribution (FA): Attributing statements or actions that are contradicted by user-provided evidence
- Deceptive Completion (DC): Claiming a task was completed when it was not.
Key findings:
- OpenAI models currently lead the Alignment Index
- Rogue actions are rare, but can have serious consequences when they occur
- Agents can mislead users about task progress
- Misalignment risks increase with conversation length
- Safety and alignment are improving across model generations
As shown in the leaderboard below (sorted by lab), @OpenAI’s GPT-6.1-Sol leads the Arena Alignment Index with a score of 87.9, followed by @AnthropicAI’s Claude-Opus-5.5 at 83.2 and @spacexai's Grok-4.7 at 82.7. OpenAI also has the best observed rates across all three signals: 0.89% Unauthorized Action, 1.98% False Attribution, and 2.34% Deceptive Completion.
Across all four labs, newer models consistently outperform their predecessors, suggesting broad progress in agent safety and alignment. As agents take on longer, more complex, and higher-stakes tasks, measuring not just what they can accomplish, but how safely and reliably they act, becomes increasingly important.
This marks an important step toward making safety and alignment a core part of how Arena evaluates AI. The index is an initial starting point, and we'll continue expanding the index with additional safety signals and models over time.
More analysis below👇
Built from 90K+ real-world agent sessions across 30 models, Arena’s Alignment Index measures three critical signals:
- Unauthorized Action (UA): Taking actions beyond the user's instructions or permissions.
- False Attribution (FA): Attributing statements or actions that are contradicted by user-provided evidence.
- Deceptive Completion (DC): Claiming a task was completed when it was not.
Dive into the Arena Alignment Index at: arena.ai/leaderboard/agent/a…
Exciting news: Muse Spark Open (Max) by @AIatMeta is the #1 US open model in the Code Arena: WebDev! With 1511 pts, it’s #13 among open models overall.
As the first open-weight release in the Muse Spark family, it scored 156 pts above Muse Glimmer, @AIatMeta’s earlier open model at #41 among open models with 1355 pts.
Priced at $1.25/$4.25 per 1M input/output tokens, it’s 79% less than Muse Wonder (Max) and priced on par with Muse Spark 1.3 (Max).
By domain, Muse Spark Open (Max) ranks:
- #13 in Brand & Marketing, and in Data & Analytics
- #14 in Reference-Based Design
- #15 Gaming, and in Consumer Product
- #20 in Simulations
Congrats to the team at @AIatMeta on this contribution to the open ecosystem!
Today we’re releasing Muse Spark Open, the most capable US open-weight model to date.
Built for coding and agentic work, it excels at long-horizon tasks, complex software engineering, and multi-step reasoning.
Key Model Specs:
→ 816B total / 42B active parameters
→ 1M token context window
→ Natively multimodal across text, image, video, audio